Wednesday, June 22, 2011

Less known facts about MySQL user grants

Reading MySQL security: inconsistencies I remembered a few related experiments that I did several years ago when I was studying for the MySQL certification. The first fact that came to mind is about the clause "WITH GRANT OPTION", which can only be given on the full set of options, not on a single grant. For example
GRANT INSERT,DELETE,UPDATE on world.* to myuser identified by 'mypass';
GRANT SELECT on world.* to myuser identified by 'mypass' WITH GRANT OPTION;
show grants for myuser\G
*************************** 1. row ***************************
Grants for myuser@%: GRANT USAGE ON *.* TO 'myuser'@'%' IDENTIFIED BY PASSWORD '*6C8989366EAF75BB670AD8EA7A7FC1176A95CEF4'
*************************** 2. row ***************************
Grants for myuser@%: GRANT SELECT, INSERT, UPDATE, DELETE ON `world`.* TO 'myuser'@'%' WITH GRANT OPTION
If you are surprised about the "WITH GRANT OPTION" clause applying to all grants instead of only applying to the SELECT, you forgot to consider how the grants are stored. All the grants for a given user (and a user is the combination of a name and a provenience) are stored in a single record in the mysql.user table. The GRANT OPTION is a column in that record. It is either set or not. You can't assign this option for only one attribute in the same record. It's either all the flagged grants or nothing. If you want to assign the "with grant option" on a single column, you must change either the provenience or the name of the user (thus opening another record). But also this addition may not be enough to reach your goal, as you can see in the next section. The other fact that came to mind about the "WITH GRANT OPTION" clause is that, in the examples given, it is ineffective. I dare say illusory. Let's start. As root user, we create this user:
root> grant all on granted.* to grantee identified by 'happyuser' with grant option;
The granted database exists, and now we have an user that can modify it, and, we think, delegate some functions to someone else.
grantee> grant select on granted.* to delegated identified by 'happy';
ERROR 1410 (42000): You are not allowed to create a user with GRANT
grantee> create user delegated;
ERROR 1227 (42000): Access denied; you need (at least one of) the CREATE USER privilege(s) for this operation
Right. I can't create a new user, but only transfer my superpowers to someone else. I will ask root to create the user, and then I will give it another try.
root>  create user delegated;
Query OK, 0 rows affected (0.00 sec)

grantee> grant select on granted.* to delegated identified by 'happy';
ERROR 1044 (42000): Access denied for user 'grantee'@'%' to database 'mysql'
Ouch! Since the grant tables are in the 'mysql' database, I don't have access. I will ask root to give me access to the mysql 'user' and 'db' tables.
root>  grant insert on mysql.user to grantee ;
Query OK, 0 rows affected (0.00 sec)
root>  grant insert on mysql.db to grantee ;
Query OK, 0 rows affected (0.00 sec)

grantee> grant select on granted.* to delegated identified by 'happy';
ERROR 1044 (42000): Access denied for user 'grantee'@'%' to database 'mysql'
Not good. I tried then to get SELECT,INSERT,UPDATE,DELETE for all the grant tables inside 'mysql'. Still, I could not exercise my grant options. Finally, the only solution was to get privilegs on the whole mysql database.
root> grant insert,select,delete,update on mysql.* to grantee;
Query OK, 0 rows affected (0.00 sec)

grantee> grant select on granted.* to delegated identified by 'happy';
Query OK, 0 rows affected (0.00 sec)
At last, I can grant something to someone.
But wait! Now that I can modify the 'mysql' database ...perhaps I could ...
grantee> update user set Select_priv ='Y',
 Insert_priv ='Y', Update_priv ='Y', Delete_priv ='Y',
 Create_priv ='Y', Drop_priv ='Y', Reload_priv ='Y',
 Shutdown_priv ='Y', Process_priv ='Y', File_priv ='Y',
 Grant_priv ='Y', References_priv ='Y', Index_priv ='Y',
 Alter_priv ='Y', Show_db_priv ='Y', Super_priv ='Y',
 Create_tmp_table_priv ='Y', Lock_tables_priv ='Y', Execute_priv ='Y',
 Repl_slave_priv ='Y', Repl_client_priv ='Y', Create_view_priv ='Y',
 Show_view_priv ='Y', Create_routine_priv ='Y', Alter_routine_priv ='Y',
 Create_user_priv ='Y', Event_priv ='Y', Trigger_priv ='Y',
 Create_tablespace_priv ='Y' where user = 'grantee';
This does not enhance my current grants, because I don't have the SUPER privilege (yet), but I can wait until the server restarts or until someone issues a 'flush privileges'. An then I will have full access to the server. Obviously, this situation is not what the DBA had in mind when the user 'grantee' was created.

Update The habit of always seeing the password set as integral part of the GRANT command has made me err on judgment.
As noted in one of the comments, the "grantee" user could have granted privileges to "delegated" without assigning a password. In this case,"grantee" does not need separate grants to the mysql database, which were apparently needed only if you wanted to set the password with the GRANT command.
All the above post is a miscalculation. The additional grants are not needed, provided that you don't include a password clause in your GRANT command.

Monday, June 20, 2011

Introducing the Tungsten-toolbox

tungsten toolbox white After the public home for Tungsten Replicator, we needed another place where to host complementary tools. We discussed the pros and cons of hosting these tools in the same place where we publish Tungsten, but in the end we decided that it's more practical to have a separate project, where we can publish tools related to database replication, no matter if they are dedicated to Tungsten or if they can work with other replication systems. So, here it is. We have now Tungsten Toolbox, a site where we will collect our tools and accept contributions from others.
We have already a few tools that, after being cleaned up, will find their way to this repository. The one that was more or less ready for prime time is the Tungsten Sandbox, a tool that installs more than one Tungsten instance with a backend database in the same host. It is, as you can imagine, based on the MySQL Sandbox and it works reasonably well. All the tools in this toolbox are released under the New BSD License. What can you expect to see in the near future? We have a few ideas already:
  • A binary log analyzer
  • A tool that changes properties on-the-fly
  • A JSON API for Tungsten
  • Sandboxes and deployers for complex topologies (multiple masters, fan-in)
  • Sandboxes and deployers for direct slaves
  • Deployers for a mix of MySQL native and Tungsten replication
  • A PostgreSQL sandbox
We are, of course, open to contributions. If you have a tool that is useful for database replication and want to release it under a BSD license, feel free to propose it in the Google Group discussion on Tungsten Replicator.

Tuesday, June 14, 2011

What happened to MySQL Forge?

Update
Soon after I posted this article, the Forge came back online! Thanks!


MySQL Forge has been offline for two days now. (2011-06-14) No sign of acknowledgement of this problem from the MySQL team. What is happening? For those not well acquainted with MySQL Forge, here are the facts. The MySQL Forge is a site that was intended to contain all community contributions. The reality did not follow the plans very closely, and some sections of the forge ended up with less contents than what should be useful. However, there are a few sections of the forge that are extremely useful to users:
  • The Wiki, which is full of irreplaceable documentation, such as the MySQL internals, description of preview features, slides and recordings of MySQL University, manual of many tools (such as the Random Query Generator, and more
  • The worklogs, or the blueprints for most MySQL features, past, present, and future
  • The tools/snippets, which is a collection of community contributed scripts. Not many, but most of them of high quality and quite useful.
I know that there was a lot of spam in the forge, but I really hope that it was taken off line on purpose. If its maintenance is a problem, I am sure we can find plenty of volunteers in the community that want to host the wiki and the rest of the useful stuff. Hello? Anybody there at Oracle/MySQL? Please give us back the forge. Thanks.

Thursday, June 09, 2011

Getting started with Tungsten Replicator and Tungsten Sandbox

We have been busy, at Continuent. In addition to our usual work with high performance replication, we have addressed usability issues, since we know that a hard-to-use problem, no matter how powerful, has low adoption. Thus, is with some personal satisfaction that I can announce the release of Tungsten Replicator 2.0.3, which comes with several huge improvements in matter of user friendliness. The new installation procedure is so user friendly, in fact, that I was able to build a sophisticated tungsten-sandbox with a 150-line shell script. (The corresponding features for MySQL Sandbox required 4,500 lines of Perl).
Enough self celebration, though. Let's get started, as the title of this post suggests, with the practical steps.

Requirements

Before we begin, there are a few requirements to meet.
  1. You need to be on a Unix-like operating system. Our main choice is Linux. If you want to test on Mac OSX, it works, but we won't recommend it.
  2. Java JRE must be installed. And it must be the original one, not the Open JDK. Update: The requirement against OpenJDK has been lifted. It works fine in my tests.
  3. Ruby 1.8 must be installed. This is mainly needed during the installation phase only, but it is required nonetheless.
  4. The user account that will install and run Tungsten must have ssh access to the other hosts involved in the cluster
  5. The above mentioned user must have sudo access. This is only needed if you want to use Tungsten Replicator to run backups that involve root access (like xtrabackup). We may lift this requirement later, but for now you need to enable it, at least during the installation, and remove the access when you are done.
  6. This user must also have read access to MySQL binary logs. Usually you achieve this by making sure that the binary logs are readable by users belonging to the "mysql" group, and by adding such group to your user.
  7. There must be a MySQL users for Tungsten replication. This user must have full access to the database server, with grant option.
  8. The MySQL server must have binary logging enabled.
  9. If you have MySQL native replication running, you must stop it.

Getting the code and install

The code is released in the downloads section of Tungsten's home. The current recommended version is 2.0.3, but if you like to be really up to date, we also publish a list of recent builds from our build server, which you can use to have a go at the replicator. For this simple installation, I will use four servers from our server farm. The servers are named R1, R2, R3, and R4. The first good news of the new installation process is this: you need to install in one server only!. More details follow. First off, create a directory where you want to install. Use a non-root account. Just make sure that it's the same user in all the servers, and that such user can access the directory where you want to install. I am going to call this directory planet.
cd $HOME
for N in 1 2 3 4 ; do ssh r$N mkdir planet ; done
cd planet 
wget http://tungsten-replicator.googlecode.com/files/tungsten-replicator-2.0.3.tar.gz
tar -xzf tungsten-replicator-2.0.3.tar.gz
cd tungsten-replicator-2.0.3
I have already a MySQL user named tungsten with password "mypwd" (but it can be anything you like, as long as it has the required privileges). Now we have all the components. If you have read the Tungsten documentation, please ignore the ./configure script. That is left for compatibility reasons, and will be deprecated soon. Instead, to install the cluster of our 4 servers, let's do the following:
export TUNGSTEN_BASE=$HOME/planet

./tools/tungsten-installer \
    --master-slave \
    --master-host=r1 \
    --datasource-user=tungsten \
    --datasource-password=mypwd \
    --service-name=dragon \
    --home-directory=$TUNGSTEN_BASE \
    --cluster-hosts=r1,r2,r3,r4 \
    --start
Some comment on this command: --master-slave is the installation mode (see below for more info). --service-name can be anything you want. --home-directory is where all the installation sub directories will go. --cluster-hosts is the list of servers you want to install, and finally, --master-host is the host that will be installed as a master, while all the others will be slaves of that one. If you have followed the instructions carefully, the installer will bring up the Tungsten cluster without any fuss, Unix style. If you hate silent installations, you can get the full monty by adding some options:
./tools/tungsten-installer \
    --verbose \
    --master-slave \
    --master-host=r1 \
    --datasource-user=tungsten \
    --datasource-password=mypwd \
    --service-name=dragon \
    --home-directory=$TUNGSTEN_BASE \
    --cluster-hosts=r1,r2,r3,r4 \
    --start-and-report
If you run the installer in verbose mode, you will see an extremely long list of validation checks that the installed does on your current servers and on the ones that are listed in the --cluster-hosts option. If everything went well, you will find the following directories in $HOME/planet (for all servers in your cluster):
  • configs, containing the configuration file created by the installer. This file describes your cluster
  • releases, containing the Tungsten binaries.
  • thl, containing Tungsten's Transaction History Logs. These logs are like MySQL binary logs, but with much more metadata, including a global transaction ID, which is missing in MySQL native replication.
  • relay, which should be empty, unless you install in "direct" mode (see below.)
  • tungsten, which is a symlink to the Tungsten directory inside releases.
In addition to the above mentioned directories, Tungsten Replicator creates a database for each service. Since we have only one service in this topology, you will find a database named "tungsten_dragon". (If you have called your service "bunny", you will instead find "tungsten_bunny"). Inside this database there is the replication metadata necessary for making the servers fault tolerant. Only a small amount of data is kept on that database. It's roughly corresponding to what you get from the .info files in MySQL native replication. To test that the system is OK, let's find our tools. The first one is trepctl, which, among other things, can give us an overview of the running services.
cd $HOME/planet
./tungsten/tungsten-replicator/bin/trepctl services
Processing services command...
NAME              VALUE
----              -----
appliedLastSeqno: 0
appliedLatency  : 1.152
role            : slave
serviceName     : dragon
serviceType     : local
started         : true
state           : ONLINE
Finished services command...

./tungsten/tungsten-replicator/bin/trepctl -host r1 services
Processing services command...
NAME              VALUE
----              -----
appliedLastSeqno: 0
appliedLatency  : 0.936
role            : master
serviceName     : dragon
serviceType     : local
started         : true
state           : ONLINE
Finished services command...

mysql -h r1 -e 'create schema if not exists test'
mysql -h r1 -e 'create table test.t1 (i int)'

./tungsten/tungsten-replicator/bin/trepctl services
Processing services command...
NAME              VALUE
----              -----
appliedLastSeqno: 2
appliedLatency  : 0.155
role            : slave
serviceName     : dragon
serviceType     : local
started         : true
state           : ONLINE
Finished services command...

./tungsten/tungsten-replicator/bin/trepctl -host r1 services
Processing services command...
NAME              VALUE
----              -----
appliedLastSeqno: 2
appliedLatency  : 0.044
role            : master
serviceName     : dragon
serviceType     : local
started         : true
state           : ONLINE
Finished services command...
After the installation, trepctl reported the last applied sequence number (appliedLastSeqno) as 0. Following the execution of two commands in the master, such number became 2. If you want to know more of what was happening, you can use the thl command. This corresponds roughly to using mysqlbinlog with MySQL native replication logs.
/tungsten/tungsten-replicator/bin/thl -service dragon list |less
SEQ# = 1 / FRAG# = 0 (last frag)
- TIME = 2011-06-09 14:51:23.0
- EVENTID = 000002:0000000000000514;197609
- SOURCEID = qa.r1.continuent.com
- STATUS = COMPLETED(2)
- METADATA = [mysql_server_id=10;service=dragon;shard=test]
- TYPE = com.continuent.tungsten.replicator.event.ReplDBMSEvent
- OPTIONS = [##charset = ISO8859_1, createOrDropDB = , autocommit = 1, sql_auto_is_null = 1, foreign_key_checks = 1, unique_checks = 1, sql_mode = '', character_set_client = 8, collation_connection = 8, collation_server = 8]
- SQL(0) = create schema if not exists test /* ___SERVICE___ = [dragon] */
SEQ# = 2 / FRAG# = 0 (last frag)
- TIME = 2011-06-09 14:51:30.0
- EVENTID = 000002:0000000000000601;197610
- SOURCEID = qa.r1.continuent.com
- STATUS = COMPLETED(2)
- METADATA = [mysql_server_id=10;service=dragon;shard=test]
- TYPE = com.continuent.tungsten.replicator.event.ReplDBMSEvent
- OPTIONS = [##charset = ISO8859_1, autocommit = 1, sql_auto_is_null = 1, foreign_key_checks = 1, unique_checks = 1, sql_mode = '', character_set_client = 8, collation_connection = 8, collation_server = 8]
- SCHEMA = 
- SQL(0) = create table test.t1 (i int) /* ___SERVICE___ = [dragon] */
Once we are satisfied that replication is working, we can clean up the cluster and try other installation experiments. To clean up a cluster, you need to do the following:
  1. stop the replicator in all servers.
    for N in 1 2 3 4; do $PWD/tungsten/tungsten-replicator/bin/replicator stop; done
  2. remove the thl files from all servers.
  3. remove the tungsten_SERVICE_NAME database from all mysql servers
  4. run a "reset master" in the master database
  5. remove the directories created by the installer in all servers

Installation types

The procedure described above was, until a few months ago, the only thing you could do with Tungsten. Now you can broaden your horizons with a wider range of possibilities.

Master/slave is of course the main option, and it's the one that you have seen in the previous section. This method gives you the full set of Tungsten features and performance. It is the recommended method for production use and for benchmarking. In this scenario, the Tungsten replicator on the master will extract transactions from the binary log, transfer them to the THL, and share it with the slaves. The slaves will read from the THL and apply the transactions to the database. There are a few steps more in between, but for the sake of brevity I will skip them You can have a look at Robert Hodges blog for more info.
Slave "direct" is the alternative that you can use in production, and it's been designed to satisfy users who only want some particular benefits on the slave side, and don't care about global transaction IDs. If you are looking at parallel apply, this is probably a setup that you want to try. In this scenario, there is no replicator on the master. The slave pulls data remotely from the binary logs, copies them locally, and extracts data to the THL. Here's an example of how to start a slave-direct system:
./tools/tungsten-installer \
    --direct \
    --master-host=r1 \
    --slave-host=r4 \
    --master-user=tungsten \
    --slave-user=tungsten \
    --master-password=secret \
    --slave-password=secret \
    --service-name=Castor \
    --thl-port=21124 \
    --rmi-port=10104 \
    --channels=5 \
    --home-directory=$TUNGSTEN_BASE \
    --start-and-report

If your purpose is testing Tungsten, probably the Tungsten Sandbox is what you should try. This system is based on MySQL Sandbox, a framework that lets you install more than one MySQL server in the same host. Building on top of MySQL Sandbox, and leveraging the new flexibility in Tungsten installer, tungsten-sandbox allows you to build a master/slave system inside a single host. Let's give it a try. You need to have MySQL Sandbox installed, and at least one MySQL tarball expanded under $HOME/opt/mysql/X.X.XX (where X.X.XX is the MySQL version, such as 5.5.12).
cd $HOME/planet
mkdir sb
cd tungsten-replicator-2.0.3
wget http://tungsten-replicator.googlecode.com/files/tungsten-sandbox
./tungsten-sandbox -h
USAGE: ./tungsten-sandbox [flags] args
flags:
  -n,--nodes:  how many nodes to install (default: 3)
  -m,--mysql_version:  which MySQL version to use (default: '5.1.56')
  -t,--tungsten_base:  where to install the sandbox (default: '/home/tungsten/tsb2')
  -d,--group_dir:  sandbox group directory name (default: 'tr_dbs')
  -s,--service:  how the service is named (default: 'tsandbox')
  -P,--base_port:  port base for MySQL sandbox nodes (default: 710)
  -l,--thl_port:  port for the THL service (default: 1211)
  -r,--rmi_port:  port for the RMI service (default: 1010)
  -v,--[no]version:  show Tungsten sandbox version (default: false)
  -h,--[no]help:  show Tungsten sandbox help (default: false)
In my server, I have already expanded MySQL 5.5.10, and I want to install inside $HOME/tsb. So, here is what I do:
./tungsten-sandbox -m 5.5.10 -t ~/tsb
This command installs three instances of MySQL under $HOME/sandboxes and three of Tungsten under $HOME/tsb. Inside this directory, in addition to the running instances, we find some more goodies:
  • clear_all send_kill_all start_all status_all stop_all use_all : symlinks to the corresponding commands in MySQL sandbox
  • db1 db2 db3: these are the tungsten instances.
  • n1 n2 n3: quick links to access each MySQL node
  • replicator_all trepctl_all: utilities that run "replicator" or "trepctl" for each node with the arguments provided on the command line
Additionally, there are a few scripts inside each Tungsten instance in the sandbox:
  • trepctl: a link to the deep down trepctl
  • thl: a link to the thl utility
  • show_log: a quick way of showing the replicator log
Since this is a tool for testing, removing it is going to be easy.
~/tsb/replicator_all stop
~/tsb/clear_all
rm -rf ~/tsb/*

A final method of installing is a sandbox with ths slave-direct method. There is no dedicated script for this method, but thanks to the new installer, you can get the job done quite easily:
export NODE_OPTIONS='-c innodb_flush_log_at_trx_commit=2 -c max_allowed_packet=48M'
make_multiple_sandbox --group_directory=tr_dbs --sandbox_base_port=7100 5.5.10

TUNGSTEN_BASE=$HOME/tinstall/tsb/
./tools/tungsten-installer \
    --direct \
    --master-host=127.0.0.1 \
    --master-port=7101 \
    --slave-host=db2 \
    --slave-port=7102 \
    --master-user=root \
    --slave-user=root \
    --master-password=msandbox \
    --slave-password=msandbox \
    --master-log-directory=$HOME/sandboxes/tr_dbs/node1/data \
    --service-name=Castor \
    --thl-port=12112 \
    --channels=5 \
    --rmi-port=20000 \
    --home-directory=$TUNGSTEN_BASE \

./tools/tungsten-installer \
    --direct \
    --master-host=127.0.0.1 \
    --master-port=7101 \
    --slave-host=db3 \
    --slave-port=7103 \
    --master-user=root \
    --slave-user=root \
    --master-password=msandbox \
    --slave-password=msandbox \
    --master-log-directory=$HOME/sandboxes/tr_dbs/node1/data \
    --service-name=Pollux \
    --thl-port=22112 \
    --channels=1 \
    --rmi-port=20000 \
    --home-directory=$TUNGSTEN_BASE \
    --relay-directory=$TUNGSTEN_BASE/relay --start-and-report
This script creates two services (Castor and Pollux), with only one instance of Tungsten replicator, with all the servers (MySQL and Tungsten ones) in the same host.

Conclusions

There should be much more to say, but I will leave it for the coming days. In the meantime, I encourage everyone to try the new Tungsten and submit bug reports when things don't work as expected. As always, happy hacking!
P.S. Today at 10am PT there is a webinar on this very topic!

Tuesday, May 17, 2011

The price of safe data - Benchmarking semi synchronous replication

Some time ago I wrote about MySQL 5.5 semi-synchronous replication. Since then, I have wanted to benchmark the overhead of semi-synchronous replication with a decent server. Now the occasion presented itself, thanks to some related business that I had to benchmark, and thus I did a few simple runs with and without semi-synchronous replication enabled, to see the impact of this feature on performance. If you haven't read the article on semi-synchronous replication, the bottom line is that, with this feature enabled, the master waits until at least one slave has acknowledged receipt for the data before returning a positive result to the client. This means that for each commit there are two network calls between master and slave. My gut feeling was that this feature would be costly in terms of query response time, although I was not prepared to such a big impact as I found out in my test. I needed a substantial set of data, and I got it by exporting the employees table from the employees test database, using one INSERT per record. Thus, I had about 300,000 records, which are a fair amount for this kind of test. Had I sent the records in a big multiple insert chunk of 10,000 records each, I would have had only 30 commits, which would not have been easy to measure. So, here goes.

regular replication
$ time mysql < employees.sql 

real 0m27.997s
user 0m1.394s
sys 0m1.046s

semi-synchronous replication
$ time mysql < employees.sql 
real 1m24.277s
user 0m3.842s
sys 0m6.270s

Semi-synchronous replication was three times slower than regular replication. The test was taken using one master in one host and one slave in two more hosts. The measurements were the same if I had only one or both slaves enabled. Using row-based replication instead of statement-based did not make any substantial impact. Now my question is: who would be prepared to accept such a performance impact for the sake of more data safety? Data is important, but response time to customers is also important. Your mileage may vary. I know many customers who would think twice before accepting this onerous trade off. I am curious to know what experience others have had with this feature, and how much performance they are willing to sacrifice for safety.

Friday, May 06, 2011

Open Database Camp 2011 opens today!

Open Database Camp 2011 The Open Database Camp 2011 opens today with the Welcome Party, starting today at 7pm CEST. The party (with good Italian food and drinks) is open to all the ones who have registered in the Attendees list.
By car you have to reach Pula, take Via Nora (Nora Street), than Via Sant'Efisio (Sant'Efisio Street), until the end, directly to the party location.
Organisers will also make a bus available on Friday 6 May, leaving from Pula Hotels (Nora Club Hotel - Villa Madau - Baia Di Nora - Is Molas - Marin Hotel - Is Morus Hotel) around 18:30 and reaching Nora. From Nora back to Pula Hotels a bus will leave around 21:00 and 22:00.
The conference itself will start on Saturday, May 7th, at 9am. Travel arrangements to reach the venue are listed in the conference wiki (wiki: Travel).
There will be a bus collecting participants from the hotels at 8:30am and the same bus from the conference venue (Sardegna Ricerche) back to the hotel in the evening.

Sessions

Open Database camp is an Un-conference. As with the previous editions, the schedule will be decided on the spot, on Saturday. You can list your intended sessions and your wishes in the Sessions page.

Logistics

You will need an ID for your wifi access. (Sorry, it's a law requirement)(*). If you want your username and password, you should collect it at the reception as soon as possible.

Customized meetings

There will be room for 1:1 meetings between attendees, if you like to do so. You will find a board with the names of all attendees and their affiliation, and you can easily schedule a meeting with them.

(*) The law has expired but after having put the fear of the state into every internet provider, the lawmakers have not said how the new regulations should be applied. Regretfully, we have still to live with the old rules.

Monday, May 02, 2011

Introducing the Flying Clusters, and more than MySQL replication

Flying Clusters My Colleague Linas Virbalas has just crossed the boundary between real and virtual and has started a blog, titled Flying Clusters.
Linas is a gifted developer who is taking care of the special projects. One of such projects is replication between MySQL and PostgreSQL, which works quite well.
Another project, which has just started, is about providing PostgreSQL with Advanced Logical Replication using Tungsten replicator. As you probably know, recent versions of PostgreSQL can do physical replication, which has its pros and cons. With this project, PostgreSQL users can also have the choice of using logical replication. Not only that: since Tungsten Replicator already supports MySQL, cross-DBMS replication clusters are not far away.
We are also more ambitious, and we are exploring ways of replicating to NoSQL entities. We will start with MongoDB at a dedicated SQL to NoSQL Replication Hackathon, where we will attempt the creation of n applier for MongoDB during the Open Database Camp conference.

Thursday, April 28, 2011

Replication : different points of view

The following quotes are the first sentences in the replication chapter of two similar books. Both are admin cookbooks. One is for PostgreSQL, one for MySQL.

Replication isn't magic, though it can be pretty cool. It's even cooler when it works, and that's what this chapter is all about.
Replication requires understanding, effort, and patience. There are a significant number of points to get right. My emphasis here is on providing simple approaches to get you started, and some clear best practices on operational robustness
PostgreSQL 9 Admin Cookbook

Replication is an interesting feature of MySQL that can be used for a variety of purposes. It can help to balance server load across multiple machines, ease backups, provide a workaround for the lack of fulltext search capabilities in InnoDB, and much more.
MySQL Admin Cookbook


The PostgreSQL quote warns of a dangerous, difficult, and unexplored path, while the MySQL one is the almost bored remark of someone whose biggest problem is to list how many good things you can do. I guess that being exposed to a given technology for longer time changes one's perception.

Wednesday, April 27, 2011

Open Database camp 2011 - Travel logistics, and don't forget the party

The Open Database Camp 2011 is near. In 9 days, the welcome party starts, and then the conference itself gets going.
If you are coming earlier than Friday, May 6th, you can either use public transportation or book a private seat with a volunteer in the car pooling page. Please help the organizers: post your arrival and departure dates and times, so we may be able to help you even outside the official conference days.
About the conference itself, as everyone should know, it's a un-conference, where the talks will be decided on the spot. But you can book ideas and topics in the sessions page.
Since we will have many participants from Italy, there will be dedicated sessions in Italian in addition to the ones in English, which is the official language of the conference.

Sunday, April 17, 2011

Replication metadata in MySQL 5.6.2

The default storage engine is InnoDB, or is it not?

When MySQL 5.5 went GA, the biggest piece of news was that the default storage engine is now InnoDB. Good news, and hope for a better future, as InnoDB is the most reliable storage engine available for MySQL.

Therefore the expectation is that MySQL 5.6 follows in its steps, and we should see less and less of MyISAM in the database.
The privileges tables, however, are still MyISAM. I was not really expecting to see them disappear so quickly, as I have seen how much work it has been for Drizzle to get rid of them, and even them had to keep MyISAM alive for temporary tables.
However, I was surprised to see that the new tables for replication metadata, the ones that replace the files master.info and relay_log.info are MyISAM by default.
The manual says:
In order for replication to be crash-safe, the slave_master_info and slave_relay_log_info tables must each use a transactional storage engine. By default, both of these tables use MyISAM; this means that, prior to starting replication, you must change both of these tables to use a transaction storage engine if you wish for replication to be crash-safe. You can do this by means of the appropriate ALTER TABLE ... ENGINE=... statements. You should not attempt to change the storage engine used by either of these tables while replication is actually running.

The funny thing is that the manual does not mention InnoDB explicitly, as if there were many transactional engines coming with the official MySQL.

Tables instead of files.

Anyway, I went ahead and tried the new metadata features. In short, the new version allows you to store the data that once were in master.info and relay_log.info in two tables with similar names, located under the mysql schema.

First of all, I changed the storage engine, as suggested by the docs. Actually, the docs are still a bit scarce about this feature. The best instructions are the ones found in Mats Kindahl.
# in the slave
ALTER TABLE mysql.slave_master_info ENGINE = InnoDB;
ALTER TABLE mysql.slave_relay_log_info ENGINE = InnoDB;

# in the slave configuration file
relay-log-info-repository=TABLE
master-info-repository=TABLE
After this operation, I initialized the two slaves, one of which has the new table info, and the other one has still the old files info, for comparison.

# slave 1 (with table info)
show slave status\G
*************************** 1. row ***************************
               Slave_IO_State: Waiting for master to send event
                  Master_Host: 127.0.0.1
                  Master_User: rsandbox
                  Master_Port: 12027
                Connect_Retry: 60
              Master_Log_File: mysql-bin.000001
          Read_Master_Log_Pos: 114
               Relay_Log_File: mysql_sandbox12028-relay-bin.000002
                Relay_Log_Pos: 267
        Relay_Master_Log_File: mysql-bin.000001
             Slave_IO_Running: Yes
            Slave_SQL_Running: Yes
[...]

select * from slave_master_info\G
*************************** 1. row ***************************
              Master_id: 101
        Number_of_lines: 20
        Master_log_name: 
         Master_log_pos: 4
                   Host: 
              User_name: 
          User_password: 
                   Port: 3306
          Connect_retry: 60
            Enabled_ssl: 0
                 Ssl_ca: 
             Ssl_capath: 
               Ssl_cert: 
             Ssl_cipher: 
                Ssl_key: 
Ssl_verify_servert_cert: 0
              Heartbeat: 1800
                   Bind: 
     Ignored_server_ids: 0
                   Uuid: 
            Retry_count: 86400


# Slave 2
cat node2/data/master.info 
20
mysql-bin.000001
114
127.0.0.1
rsandbox
rsandbox
12027
60
0


0
1800.000

0
6cb60e24-68e7-11e0-9eec-6c626da07446
86400

Hmmm. Not good. Definitely not good.
Now, according to Mats article, the slave_master_info table is updated every time a slave starts. But this is not the case.
Apparently, you need to restart it at least once more, to get an update.
# slave 1
stop slave; 
start slave;
select * from slave_master_info\G
*************************** 1. row ***************************
              Master_id: 101
        Number_of_lines: 20
        Master_log_name: mysql-bin.000001
         Master_log_pos: 114
                   Host: 127.0.0.1
              User_name: rsandbox
          User_password: rsandbox
                   Port: 12027
          Connect_retry: 60
            Enabled_ssl: 0
                 Ssl_ca: 
             Ssl_capath: 
               Ssl_cert: 
             Ssl_cipher: 
                Ssl_key: 
Ssl_verify_servert_cert: 0
              Heartbeat: 1800
                   Bind: 
     Ignored_server_ids: 0
                   Uuid: 6cb60e24-68e7-11e0-9eec-6c626da07446
            Retry_count: 86400

This lack of update is the default by design. The reasoning is that if you update the table at every transaction, you are slowing down replication beyond acceptable levels. However, it must be noted that the update of the table is way less than the updates of the file.

You can force the slave_master_info and slave_relay_log_info tables to update at every transaction, by setting sync_master_info and sync_relay_log_info. Indeed, with this addition, the table is updated at every transaction.
Therefore the choice is between crash unsafe and fast (with the *.info files) and crash safe and very slow (with the tables).

Usability issues


Let's mention the good news first. This addition is very welcome, because it allows monitoring tools to be implemented directly in SQL. The main difficulty about this problem is that the only metadata available until MySQL 5.5 is "SHOW SLAVE STATUS", which has no related Information_Schema or Performance_Schema table. Thus, getting the status values into a SQL variables is not feasible without external tools. This metadata is no replacement for SHOW SLAVE STATUS (that worklog is still struggling with a slow implementation) but there is enough overlapping that a simple monitoring tool could be created with SQL, stored routines and the event scheduler.

Now, for the bad news:
This implementation leaves me baffled for several reasons.
The lack of updates by default is the biggest concern. There is no option of automatic updates every second, same as synch_binlog. It's all or nothing.

The choice of implementation is not pleasant either. Users would expect the table-based recording to mimic the behavior of the file-based recording, i.e. when replication is started, the table is created, and after a "reset slave' the table is removed. But this does not happen. The table is truncated, and if you remove it, it won't be created when you restart replication.

What's worse, this table can't be dumped with locks. MySQL complains if you attempt to do that.
./s1 -e 'stop slave'

mysqldump mysql slave_master_info
-- MySQL dump 10.13  Distrib 5.6.2-m5, for linux2.6 (x86_64)
--
-- Host: localhost    Database: mysql
-- ------------------------------------------------------
-- Server version 5.6.2-m5-log

/*!40101 SET @OLD_CHARACTER_SET_CLIENT=@@CHARACTER_SET_CLIENT */;
/*!40101 SET @OLD_CHARACTER_SET_RESULTS=@@CHARACTER_SET_RESULTS */;
/*!40101 SET @OLD_COLLATION_CONNECTION=@@COLLATION_CONNECTION */;
/*!40101 SET NAMES utf8 */;
/*!40103 SET @OLD_TIME_ZONE=@@TIME_ZONE */;
/*!40103 SET TIME_ZONE='+00:00' */;
/*!40014 SET @OLD_UNIQUE_CHECKS=@@UNIQUE_CHECKS, UNIQUE_CHECKS=0 */;
/*!40014 SET @OLD_FOREIGN_KEY_CHECKS=@@FOREIGN_KEY_CHECKS, FOREIGN_KEY_CHECKS=0 */;
/*!40101 SET @OLD_SQL_MODE=@@SQL_MODE, SQL_MODE='NO_AUTO_VALUE_ON_ZERO' */;
/*!40111 SET @OLD_SQL_NOTES=@@SQL_NOTES, SQL_NOTES=0 */;
mysqldump: Got error: 1721: You can't use locks with rpl info tables. when doing LOCK TABLES
This makes more difficult the operation of provisioning a slave from a backup. I would expect that, having stopped the slave, I could backup the table, possibly together with the rest of the database. Maybe MySQL has a hidden clever way of exporting this data, but if that exists, so far it has escaped me.

Update: You can use the following command to dump this table.
mysqldump --master-data mysql slave_master_info
However, a simple
mysqldump --master-data mysql
does not include the *_info tables. (Bug#60902)

Another problem is maintenance. If I want to clean up the InnoDB table space, the usual recipe is to dump everything, stop the server, remove the ib* files, restart the server, and then reload the data.
That has worked very well so far, because there were no innodb tables in the mysql database. Now, however, if we attempt to perform the above operation, we get an error when InnoDB comes online, because it won't find an internal reference to the innodb tables, whose .frm files (and possibly .ibd files) are still dangling around under the mysql folder.

Incidentally, I can note that Tungsten Replicator uses a similar approach (replication metadata is stored in a table, which is updated at every commit), and yet it does not suffer from any of the drawbacks mentioned here. The replication metadata tables are stored in a regular schema, which can be dumped just fine to provision a new slave. The additional commits are not a problem, since Tungsten uses the technique of block commits, where it commits together all the transactions that can be safely grouped.
The safety of the slave thus depends on the value of --innodb-flush-log-at-trx-commit, not on additional trade off decisions.

More to come.

This article covers just a portions of the replication improvements in 5.6. There is much more to see and test.
Specifically, I want to test the performance impact of the metadata tables, and also the performance of the multi-threaded slave prototype against regular replication and Tungsten. I will get around to it shortly. Stay tuned.

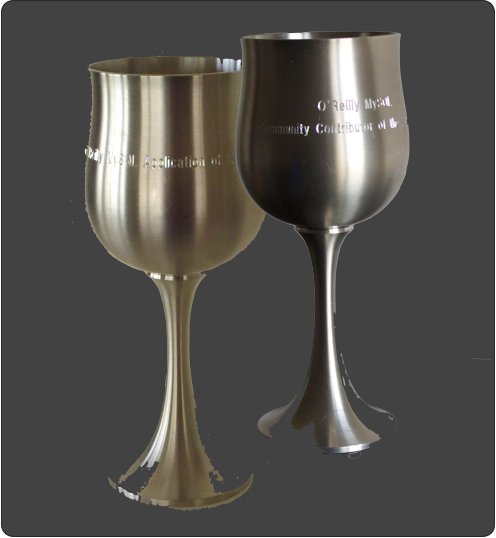
Pewter for Tungsten - Thanks, MySQL community!

community awards 2011 After the opening keynote at the MySQL Conference, there was the usual ceremony of the MySQL community awards. Since Oracle declined to continue in the MySQL AB tradition of awarding the contributions from the community, the community itself has taken over.
I was pleasantly surprised to find my name among the recipients, and even more about the prize awarded to my company's product, the Tungsten Replicator.
The surprise comes because we have been making noise about this product for only a few months, after we finalized our plans to split the company products between open source and enterprise. Apparently, it has been the right kind of noise, and the community has been able to see that Tungsten is a tangible contribution to the MySQL ecosystem.
Now that the MySQL Conference's frenzy is over, we can continue making Tungsten even better than it is today. As probably everyone knows, we have found a generous sponsor (which should remain unnamed for now, but to whom we are very grateful) that is paying for implementing and strengthening the features that will make Tungsten 2.0 production ready in the near future.
If users want to contribute with their feedback, they can download the binaries (and the full source code) from the new Tungsten home http://tungsten-replicator.org, and report issues in the same site. See Settling in at code.google.com for more information.
More technical info will follow soon.
For now, I just wanted to say Thank you, MySQL community!

Friday, April 15, 2011

Have you missed the MySQL Conference? Come to OpenDbCamp!

opendbcamp The MySQL Conference is over. There have been many new developments, and the ones who have missed it will probably want to get a summary of the excitement, possibly from the people who have contributed to shaping the news.
The Open Database Camp will give users an opportunity to catch up. Especially to open source users in Europe.
Come and share the fun. There will be talks on MySQL, PostgreSQL, several NoSQL products, and a bunch of other cool stuff.

Thursday, April 07, 2011

Refactored again: poor man's MySQL replicator monitor

I saw that both Haidong Ji and Geert VanderKelen have proposed a Python monitor for MySQL replication, calling it the "poor man's version".
See Poor man’s MySQL replication monitoring and Geert's Refactored: Poor man’s MySQL replication monitoring.
Having Python in your server doesn't really qualify as "poor man". In many cases it's a luxury, and thus, here's my shot at the problem, using a Bash shell script.
Unlike its Python-based competition, this version also checks that the slave is replicating from the intended master, and that it is not lagging behind.
#!/bin/bash

USERNAME=msandbox
PASSWORD=msandbox
EXPECTED_MASTER_HOST=127.0.0.1
EXPECTED_MASTER_PORT=27371

SLAVE_HOST=127.0.0.1
SLAVE_PORT=27372

MYSQL="mysql -u $USERNAME -p$PASSWORD "
MASTER="$MYSQL -h $EXPECTED_MASTER_HOST -P $EXPECTED_MASTER_PORT"
SLAVE="$MYSQL -h $SLAVE_HOST -P $SLAVE_PORT"

$MASTER -e 'SHOW MASTER STATUS\G' > mstatus
$SLAVE -e 'SHOW SLAVE STATUS\G' > sstatus

function extract_value {
    FILENAME=$1
    VAR=$2
    grep -w $VAR $FILENAME | awk '{print $2}'
}

Master_Binlog=$(extract_value mstatus File )
Master_Position=$(extract_value mstatus Position )

Master_Host=$(extract_value sstatus Master_Host)
Master_Port=$(extract_value sstatus Master_Port)
Master_Log_File=$(extract_value sstatus Master_Log_File)
Read_Master_Log_Pos=$(extract_value sstatus Read_Master_Log_Pos)
Slave_IO_Running=$(extract_value sstatus Slave_IO_Running)
Slave_SQL_Running=$(extract_value sstatus Slave_SQL_Running)

ERROR_COUNT=0
if [ "$Master_Host" != "$EXPECTED_MASTER_HOST" ]
then
    ERRORS[$ERROR_COUNT]="the slave is not replicating from the host that it is supposed to"
    ERROR_COUNT=$(($ERROR_COUNT+1))
fi

if [ "$Master_Port" != "$EXPECTED_MASTER_PORT" ]
then
    ERRORS[$ERROR_COUNT]="the slave is not replicating from the host that it is supposed to"
    ERROR_COUNT=$(($ERROR_COUNT+1))
fi

if [ "$Master_Binlog" != "$Master_Log_File" ]
then
    ERRORS[$ERROR_COUNT]="master binlog ($Master_Binlog) and Master_Log_File ($Master_Log_File) differ"
    ERROR_COUNT=$(($ERROR_COUNT+1))
fi

POS_DIFFERENCE=$(echo ${Master_Position}-$Read_Master_Log_Pos|bc)

if [ $POS_DIFFERENCE -gt 1000 ]
then
    ERRORS[$ERROR_COUNT]="The slave is lagging behind of $POS_DIFFERENCE"
    ERROR_COUNT=$(($ERROR_COUNT+1))
fi

if [ "$Slave_IO_Running" == "No" ]
then
    ERRORS[$ERROR_COUNT]="Replication is stopped"
    ERROR_COUNT=$(($ERROR_COUNT+1))
fi

if [ "$Slave_SQL_Running" == "No" ]
then
    ERRORS[$ERROR_COUNT]="Replication (SQL) is stopped"
    ERROR_COUNT=$(($ERROR_COUNT+1))
fi

if [ $ERROR_COUNT -gt 0 ]
then
    EMAIL=myname@gmail.com
    SUBJECT="ERRORS in replication"
    BODY=''
    CNT=0
    while [ "$CNT" != "$ERROR_COUNT" ]
    do
        BODY="$BODY ${ERRORS[$CNT]}"
        CNT=$(($CNT+1))
    done
    echo $SUBJECT
    echo $BODY
    echo $BODY | mail -s "$SUBJECT" $EMAIL
else
    echo "Replication OK"
    printf "file: %s at %'d\n" $Master_Log_File  $Read_Master_Log_Pos
fi

Monday, April 04, 2011

Make your voice heard. Tell Oracle and the MySQL Council what bugs you

The MySQL Council has not being idle. We have addressed the bugs database concerns, and we are continuing our dialog.
To do a better job, we would like to hear more from the community. Unlike other established user groups, MySQL does not have a world wide organization for its users. The council exists on a voluntary basis, and we are seeking support from the rest of you. Please let your voice heard. There are three main channels for this:
  • A MySQL Council survey
  • A set of questions that will be answered during the keynote at the MySQL Conference
  • Talk to a council member

Survey

The MySQL Council survey is an attempt to collect, understand, and eventually prioritize what the MySQL community feels, and act on their suggestions. It is a very short survey. We don't want your opinion on everything from barbecue sauce recipes to brain surgery. We need only a few lines about what bothers you the most with MySQL and how we can help. And of course, if you wamt to help, we really want to hear about that.

Questions for the keynote

Let's ask Oracle directly. What are the biggest issues that you have? You can submit your questions for the keynote, and Tomas Ulin will answer them on stage at the MySQL conference
Here is your shot at practicing people power: think of the most pressing questions that you would see Tomas Ulin addressing, and submit them as soon as possible.

Talk to a council member

Council members are all well known people in the community. Most of us will be at the MySQL Conference or at Collaborate 11, or both.
If you want to ask me questions about the council, or MySQL, or community matters, I will do my best to answer them, or to seek an answer if I don't know it myself.

I will be at the San Francisco MySQL User Group on April 7th.
Then I will be at the MySQL conference Monday and Tuesday. Oh, and there is the Community Dinner West on Monday evening!
On Wednesday, I will be at Collaborate 11.
The other council members will be around as well. If you don't feel like filling the survey and prefer person-to-person communication, come see us, and let's talk!

Open Database camp 2011 - Opportunities for sponsors, culture, and more

The Open Database Camp 2011 is barely one month away.

Sponsorship

Many thanks to all the sponsors! We very much appreciate your support.
Speaking of what, here is some important information for sponsors: The venue owners, Sardegna Ricerche, has given us the availabilkity of an ample hall for sponsors, where they can showcase their products and services.
Each sponsor will have a desk, and a double panel sized cm 195 x 75 (6.3 x 2.4 feet).

Culture, fun, and more

The Science park is something unique that geeks may want to visit. It is one of the biggest research centers in Europe, and the owners have graciously organized a guided tour before and after the conference.
Near the conference there is Nora, an archeological site that alone is worth the trip for a visit. You can see it during the welcome party on Friday (if you show up before sunset, that is), or you can visit on your own after the conference.

To give you an idea of what expects you, here is a promotional video of Sardegna Ricerche.


More

The event should attract many local open source enthusiasts, with varying degrees of knowledge about open database. To meet their curiosity, there will be a parallel beginners track, with introductory sessions to open databases. SQL and noSQL fans, get ready to evangelize your beloved products. There will be many people eager to listen!

Thursday, March 31, 2011

MySQL replication for demanding users

I have been working with MySQL replication for quite a while. I have dealt with simple replication setups and I have experimented with complex ones. Five years ago I wrote an article about advanced MySQL replication, which was mostly a dream on what you could do with imagination and skill, but the matter from that article is still not even remotely ready for production. Yet, since that article, I have been approached by dozens of people who wanted to know how to make the multiple master dream become reality. To all of them, I had to say, "sorry, this is just a proof of concept.Come back in a few years, it may become possible". It still isn't.
Despite its latest great technological advance, MySQL native replication is is very poor of topologies. What you can do with MySQL native replication is master-to-slave (which also includes relayed slaves), master-to-master, and circular replication.
replication topologies
Of these, circular replication is the closest thing to multiple masters that you can get with MySQL native replication, without the addition of third party services.
Circular replication is tricky to set up, although not unreasonably so. It works. With some patience and precision, you can build a cluster of a few nodes in circular replication. With luck, you can get them to work properly, without loops and with the data flowing to all the servers. Your luck runs out the moment one of the servers fails, or replication breaks down for whatsoever reason. Then you see that circular replication is actually more complicated than what it looks on the surface, and it is also quite brittle. That doesn't mean that circular replication is not used in production. It is. I have known several people who use it successfully, although nobody is really happy about it.
In addition to its fragility, circular replication is slow. If you insert data into master A, it has to travel across three nodes before reaching master D.
Another topology that seems to be very popular is the multiple source scheme. It is the opposite of master/slave. Instead of having one master that sends data to many slaves, it is many masters that send data to one slave. Despite its popularity, this topology is yet unimplemented with MySQL native replication. The best you can do to simulate the desired outcome is to do round-robin replication with cron.
With this background, it is no surprise that I was thrilled at the idea of working for a company that has made these dreams become reality. Tungsten replicator allows users to have real multiple masters topologies, and even the much coveted multiple source topology is now within the users grasp.
Compared to MySQL replication, the drawback of using Tungsten is that you need to deal with bigger complexity. It's only natural. With so many more features, there come more pieces to take care of.
An interesting point about multiple masters is the matter of conflict resolution. Asynchronous replication convenience and robustness are countered by lack of means to deal with conflicts. This difficulty has been used many times as the reason for not implementing multiple source replication in MySQL. I have my own ideas on this issue. I am aware of the risks, but if I were allowed to do multiple master replication, I would be glad to take charge of the risks. Updating different databases, or different tables in separate masters is one way of defining a conflict-free scenario where multiple masters or multiple sources could be used safely. If only we could ...
My colleague Robert Hodges has posted some interesting aspects in his blog. The bottom line is that we focus on empowering users with advanced replication features. Conflict resolution can wait. I am sure many users would love to have the problem of how to avoid conflicts if the more demanding problem of how to replicate from many places to one cluster could be solved. The good news is that some sort of conflict detection (and possibly resolution) are possible even now, without slowing down the operations and without complicating our lives unnecessarily. For example, a simple conflict that could be avoided using Tungsten filters is the one resulting in a master that is updating tables that it was not supposed to do. In a scenario where multiple source replication works on the assumption that each master updates a given subset of the data, we can easily detect and eventually reject offending updates. It is not much, but in many practical cases it would be the difference between having robust multiple source replication and doing data load and consolidation manually.

Anyway, back to the present day with very much real multi-master replication available for everyone. To alleviate the fear of the unknown, we are organizing webinars on a regular basis, where we cover the theoretical points and give practical demos of how to use the new features.
If you are a demanding user, this upcoming webinar is for you: MySQL Multi-Master and Multi-Source Replication With Tungsten. Tomorrow, March 31st, 2011, at 10am PDT.

Thursday, March 17, 2011

How fast is parallel replication? See it live today

I talked about parallel replication last month. Since then, there has been a considerable interest for this feature. As far as I know, Tungsten's is the only implementation of this much coveted feature, so I can only compare with MySQL native replication.
The most compelling question is "how fast is it?"
That's a tricky one. The answer is the same that I give when someone asks me "how fast is MySQL". I always say: it depends.
Running replication in a single thread is sometimes slower than the operations in the master. Many users complain that the single thread can't keep up with the master, and the slave lags behind. True. There is, however, a hidden benefit of single threaded replication: it requires less resources. There is no contention for writing on disk, no need to worry about several users blocking a table. You need to contend with the users that want to read the tables, but the lone writer has an easy job, albeit a hard one.
When we introduce parallel replication, the easy job fades away, and we are faced with the problem: how do I allow several writers to do the work of one? It's a nice problem to have. MySQL native replication does not allow parallel apply, but with Tungsten you can start tackling the issue of allowing several parallel threads to update the system at once. Therefore, this is the same problem that you have on a server where several users are allowed to write at once. If the server has sufficient resources, the operations will be fast. If it doesn't, the operations will lag behind.
Another aspect of the question is "what kind of queries?" If your database is well established and set in stone, and you mostly UPDATEs, the replication performance will depend on how well your server is tuned for concurrent writes. If you run ALTER TABLE statements on a daily basis, your queries will queue up after that ALTER TABLE no matter what. And if you have only INSERT and DELETE queries, parallel replication will probably depend on how fast is your server.
Ultimately, I can tell you that I have seen or experienced directly a wide range of repeatable results. I know cases where parallel replication is three times as fast as native replication. These cases usually involve huge amounts of binary logs, like in the case when your slave needs to be taken off-line for a few hours or even days and then it tries to catch up. Other cases that can be reproduced with a minimal amount of sample data show parallel replication as being 30% to 50% faster. ANd then there are cases when your server is so poor on resources or the load is so unevenly distributed that parallel replication is as fast as native replication. I would say that these cases are easily cured by beefing up the server.
If you want to see a demo of how this replication works, you can join this webinar:
Zoom, Zoom, Zoom! MySQL Parallel Replication With Tungsten Replicator 2.0.
You can tell from the title that we are quite excited about the product that we are building.

Tuesday, March 15, 2011

Quick benchmarking trick

I have been doing quite a lot of benchmarking recently.
I needed to find a safe way of measuring the time spend by the database doing a long task, like catching up on a huge backlog of accumulated replication updates. The problem with measuring this event is that I can record when it starts, but I can't easily detect when it finishes. My initial approach was to monitor the database and count the tables rows to see when the task was done, but I ended up affecting the task performance with my additional queries. So I thought of another method.
Since I had control on what was sent from the master to the slave, I used the following:
The initial time is calculated as the minimum creation time of the databases that I know are created during the exercise. Let's say that I had 5 databases named from db1 to db5:
set @START = (select min(create_time) from information_schema.tables where table_schema like "db%")
Then, to make sure that I catch the exact moment that the task is finished, I added to the master a command for each database:
create table db1.last_table (i int);
create table db2.last_table (i int);
create table db3.last_table (i int);
create table db4.last_table (i int);
create table db5.last_table (i int);
To know if the task is done, I query the database as follows:
select count(*) from information_schema.tables where table_schema like "db%" and table_name="last_table";
If the count is less than 5 (the number of databases that were in my binary logs), I wait more.
Finally, when the count matches the expected one, I get the end time:

set @END = (select max(create_time) from information_schema.tables where table_schema like "db%" and table_name="last_table"');
Now I have two values, @START, and @END
select timediff(@END,@START) as elapsed;
+----------+
| elapsed  |
+----------+
| 00:09:44 |
+----------+
It does not matter if I query the database immediately, or hour after coming back from my errands. Using the table creation times makes sure that I get a clean start and finish time.
I put all the above in a script, and I can check the elapsed time without fear of mistakes.

Sunday, March 13, 2011

A cool terminal tip for Mac users

If you use a Mac, and you are dealing with many similar tasks at once, like examining many database servers in different terminals, you may like this one.
I have been using iTerm 2 for a while, and my handling of parallel tasks has improved a lot. (No, I am not talking about Parallel replication, although I have applied this trick while testing that technology as well.)
iTerm2 has some cool features, and probably the most striking one is split panes. That alone would be a good reason for giving iTerm2 a try. But the one that I use the most, often in combination with Split Panes, is called Send Input to all tabs.
Here is how it works.
Let's say I need to use 4 servers at once, and perform a non-repeating operation in all of them.
So I open a separate window and I split the screen into 5 panes. I connect to each server in the first four panes, and I open a vim instance in the fifth.
With that done, I enable the magic option.


A word of caution. This option sends the input to all the open tabs in your current window. If you don't want this to happen, do as I do, and open a separate window. Then make sure that all tabs, and eventually split panes, are supposed to receive your input. The application asks you for confirmation.


After that, whatever I type on one pane will be mirrored on all the panes. So I will see the commands running on my four servers, and being logged in a text file in the fifth one. All with just single command, I have all servers under control at once:

Replication and sandbox talks on the road - San Francisco, Santa Clara, Orlando

In a few weeks, I will be on the road, for an intense set of presentations in the USA.

San Francisco, April 7th

I will start the tour at the San Francisco MySQL User Group. On April 7, at 6pm I will talk about Advanced MySQL replication for the masses. This talk will explore topics such as bi-directional replication, multiple sources, parallel replication, seamless failover, with the help of Tungsten replicator.


O'Reilly MySQL Conference & Expo 2011

Santa Clara, April 11, 12

The MySQL conference starts on Monday, April 11th, with several three-hour tutorials.

Robert Hodges and Edward Archibald will also be presenting at the MySQL Conference.

On Tuesday evening I will fly to Orlando, to attend (part of) Collaborate11.

collaborate11 badge

Orlando, April 13