Thursday, August 31, 2006
MySQL Sandbox tutorial reprinted by (IN)SECURE magazine
The latest issue of (IN)SECURE magazine, a freely available digital security magazine discussing some of the hottest information security topics, is featuring a reprint of my introduction to MySQL Sandbox.


Friday, August 11, 2006
MySQL Federated Engine: the missing manual
If you have used the MySQL Federated engine, you may share my opinion that it's perhaps the most amazing feature introduced in recent versions, far more interesting and promising than other more advertised ones.
If you have used it, though, you must have noticed how skinny is the official manual. There are countless questions popping from your head while testing this feature, and no answers in sight.
Errata: you can safely ignore the lines mentioning foreground in the color codes table. The producer has not rendered it the way it should have been. It will be hopefully fixed soon.
If you have used it, though, you must have noticed how skinny is the official manual. There are countless questions popping from your head while testing this feature, and no answers in sight.
 | Well, take heart! The missing manual for the Federated Engine was just released. As any missing manual, it is not an official document, but just a collection of many practical things I found out in my daily usage. There must be much more to find and to try, but for now, enjoy this article as the first step toward being productive with the Federated engine. |
Errata: you can safely ignore the lines mentioning foreground in the color codes table. The producer has not rendered it the way it should have been. It will be hopefully fixed soon.
Monday, July 31, 2006
MySQL Sandbox tutorial translated in Portuguese
A while ago I wrote a tutorial on the MySQL Sandbox.
Wallace Reis asked me permission to translate it, and I happily agreed.
And now there it is: the tutorial Portuguese translation (the first part, but the rest will come).
Thanks, Wallace!
Wallace Reis asked me permission to translate it, and I happily agreed.
And now there it is: the tutorial Portuguese translation (the first part, but the rest will come).
Thanks, Wallace!
Friday, July 28, 2006
An ugly query should be a warning bell
A recent question in a newsgroup was
However, the poster added hastily that his request was wrong, and that what he identified as "numbers" are actually character strings of various length, thus making my solution much harder to find. The sample given was
Therefore, the right course of action would be to split the table:
This way, the ugly query to sort by "how many pipes" would be reduced to the simple
Beware of ugly queries. Often they tell you that something in your structure design may be wrong.
Suppressing my urge to say something about the data structure, I suggested this clever solution from a test sample I deduced from the request:
Given this table in MySQL 4.0, how can I run a single query to sort the records by the number of pipes in myfield?id(int) -------- myfield(varchar)
1 --------- |number1|number2|
2 --------- |number1|
3 --------- |number1|number2|number3|
4 --------- |number1|number2|number3|number4|
select * from mytable;
+----+-------------------+
| id | myfield           |
+----+-------------------+
|  1 | 10|1|12|9         |
|  2 | 1|2               |
|  3 | 19|5|59|91        |
|  4 | 111|31|10|1|12|9  |
|  5 | 1|2|7             |
|  6 | 95|59|91          |
|  7 | 123456789|2000000 |
+----+-------------------+

select id, myfield,
replace(
replace(
replace(
 replace(
  replace(
   replace(
    replace(
     replace(
      replace(
       replace(myfield,
       '9',''),
      '8',''),
     '7',''),
    '6',''),
   '5',''),
  '4',''),
 '3',''),
'2',''),
'1',''),
'0','') as so
from mytable
order by so;
+----+-------------------+-------+
| id | myfield           | so    |
+----+-------------------+-------+
|  2 | 1|2               | |     |
|  7 | 123456789|2000000 | |     |
|  5 | 1|2|7             | ||    |
|  6 | 95|59|91          | ||    |
|  1 | 10|1|12|9         | |||   |
|  3 | 19|5|59|91        | |||   |
|  4 | 111|31|10|1|12|9  | ||||| |
+----+-------------------+-------+
However, the poster added hastily that his request was wrong, and that what he identified as "numbers" are actually character strings of various length, thus making my solution much harder to find. The sample given was
But then I overcame my desire of showing off with my cunning solutions, and told him that, apart for the initial misunderstanding about numbers and strings, his table was stained with the unforgivable sin of not being even in 1NF.
1 --------- |ruote in lega|macchine gialle|
2 --------- |case in affitto|
3 --------- |treni|vagoni|camini|
Therefore, the right course of action would be to split the table:
contents
1  ruote in lega
2  macchine gialle
3  case in affitto
4  treni
5  vagoni
6  camini

mytable
ID id_content
1  1
1  2
2  3
3  4
3  5
3  6
This way, the ugly query to sort by "how many pipes" would be reduced to the simple
SELECT id, count(*) as how_many
from mytable inner join contents using (id_content)
group by id
order by how_many
Beware of ugly queries. Often they tell you that something in your structure design may be wrong.
Monday, July 17, 2006
Obscure settings
I remember when MySQL was spreading rapidly, mostly due to its ease of use. That was long time ago, apparently. Now we are entering the dark ages of obscure settings, or so it seems, reading some MySQL Cluster setting definitions.
Quoting from the the manual:
Any suggestions for taking this definition down to planet Earth?
Quoting from the the manual:
TimeBetweenLocalCheckpoints
This parameter is an exception in that it does not specify a time to wait before starting a new local checkpoint; rather, it is used to ensure that local checkpoints are not performed in a cluster where relatively few updates are taking place. In most clusters with high update rates, it is likely that a new local checkpoint is started immediately after the previous one has been completed.
The size of all write operations executed since the start of the previous local checkpoints is added. This parameter is also exceptional in that it is specified as the base-2 logarithm of the number of 4-byte words, so that the default value 20 means 4MB (4 × 220) of write operations, 21 would mean 8MB, and so on up to a maximum value of 31, which equates to 8GB of write operations.
Any suggestions for taking this definition down to planet Earth?
Thursday, July 06, 2006
Measuring MySQL resources consumption on Linux
If you have ever felt the need of measuring how much of your resources a MySQL process is eating up, you're welcome to share my experience on the subject, reading Measuring resources for a MySQL server on Linux, which also introduces mysqlresources, a new command line tool that gets your server's statitics from the operating system and prints a nice report.
With MySQL, it's easy to get statistics from the server itself, but sometimes you need a view from the outside. mysqlresources does just that. Read on.
With MySQL, it's easy to get statistics from the server itself, but sometimes you need a view from the outside. mysqlresources does just that. Read on.
Wednesday, July 05, 2006
A first taste of logs on demand
From time to time I install MySQL from the development tree, to see what's new, and in the latest one I found a pleasant surprise:
This feature was long overdue. Well done!
Welcome to the MySQL monitor.  Commands end with ; or \g.
Your MySQL connection id is 3 to server version: 5.1.12-beta

Type 'help;' or '\h' for help. Type '\c' to clear the buffer.

mysql [localhost] {datacharmer} ((none)) > show variables like "%log";
+--------------------------------+-------+
| Variable_name                  | Value |
+--------------------------------+-------+
| back_log                       | 50    |
| general_log                    | OFF   |
| innodb_locks_unsafe_for_binlog | OFF   |
| log                            | OFF   |
| slow_query_log                 | OFF   |
| sync_binlog                    | 0     |
+--------------------------------+-------+
6 rows in set (0.00 sec)

mysql [localhost] {datacharmer} ((none)) > select * from mysql.general_log;
Empty set (0.01 sec)

mysql [localhost] {datacharmer} ((none)) > set global general_log=1;
Query OK, 0 rows affected (0.01 sec)

mysql [localhost] {datacharmer} ((none)) > select * from mysql.general_log;
+---------------------+-----------------------------------------+-----------+-----------+--------------+---------------------------------+
| event_time          | user_host                               | thread_id | server_id | command_type | argument                        |
+---------------------+-----------------------------------------+-----------+-----------+--------------+---------------------------------+
| 2006-07-05 17:26:56 | datacharmer[datacharmer] @ localhost [] |         3 |         0 | Query        | select * from mysql.general_log |
+---------------------+-----------------------------------------+-----------+-----------+--------------+---------------------------------+
1 row in set (0.04 sec)

mysql [localhost] {datacharmer} ((none)) > select * from mysql.general_log;
+---------------------+-----------------------------------------+-----------+-----------+--------------+---------------------------------+
| event_time          | user_host                               | thread_id | server_id | command_type | argument                        |
+---------------------+-----------------------------------------+-----------+-----------+--------------+---------------------------------+
| 2006-07-05 17:26:56 | datacharmer[datacharmer] @ localhost [] |         3 |         0 | Query        | select * from mysql.general_log |
| 2006-07-05 17:27:08 | datacharmer[datacharmer] @ localhost [] |         3 |         0 | Query        | select * from mysql.general_log |
+---------------------+-----------------------------------------+-----------+-----------+--------------+---------------------------------+
2 rows in set (0.00 sec)

mysql [localhost] {datacharmer} ((none)) > set global general_log=0;
Query OK, 0 rows affected (0.01 sec)

mysql [localhost] {datacharmer} ((none)) > select * from mysql.general_log;
+---------------------+-----------------------------------------+-----------+-----------+--------------+---------------------------------+
| event_time          | user_host                               | thread_id | server_id | command_type | argument                        |
+---------------------+-----------------------------------------+-----------+-----------+--------------+---------------------------------+
| 2006-07-05 17:26:56 | datacharmer[datacharmer] @ localhost [] |         3 |         0 | Query        | select * from mysql.general_log |
| 2006-07-05 17:27:08 | datacharmer[datacharmer] @ localhost [] |         3 |         0 | Query        | select * from mysql.general_log |
| 2006-07-05 17:27:11 | datacharmer[datacharmer] @ localhost [] |         3 |         0 | Query        | set global general_log=0        |
+---------------------+-----------------------------------------+-----------+-----------+--------------+---------------------------------+
3 rows in set (0.00 sec)
This feature was long overdue. Well done!
Tuesday, June 20, 2006
Talking at FrOSCon 2006
I will be at FrOSCon 2006 on June 24, with a talk about Pivot tables in MySQL 5.
I will arrive in Sankt Augustin on June 23, flying from Alghero Fertilia, Italy to Frankfurt Hahn, Germany and then driving to the conference site (travel plan).
The funny thing is that, when I booked my flight, I had no idea that I was about to get in the middle of the Soccer World Cup. Being no soccer fan, I realized this fact only when the media circus started and I could not avoid being informed. Oh, well, now I understand why it wasn't easy to find a hotel, even booking two months in advance!
The slides and the source code for this talk are available from my site.
Friday, June 02, 2006
Filling test tables quickly
Let's say that you are building a new application, and you need to test it against a large set of data. You would need either to borrow the data from some known source or to create it yourself.
Even without a stored procedure, you could just insert a line manually and then execute 20 times this query:
And it should not take you more than 30 seconds.
Since we need unique words, we can ask the database to produce the missing half by reversing the existing ones.
Then, if we want records with one minute interval, we can proceed like this:
There are other techniques as well, but these three are techniques that you can use to get the job done even without dedicated tools.
If you have such collection at your disposal, good for you. But more often than not you need some sort of data that is not ready in your repositories, and then you need to have a quick method to create it.
I will tell you three quick tricks to create large datasets of simple data types, namely numbers, words, and dates.Le's assume that we need at least one million records. Here's how to go for it.
numbers
Creating a large table with just a numeric field is quite simple.You may be tempted to run a loop in your favorite language, or even in a SQL stored procedure, but this approach would run for quite a long time.
There is a better solution, that will fill your large table in a few seconds
drop table if exists numbers;
create table numbers ( id int not null primary key);

delimiter $$

drop procedure if exists fill_numbers $$
create procedure fill_numbers()
deterministic
begin
  declare counter int default 1;
  insert into numbers values (1);
  while counter < 1000000
  do
      insert into numbers (id)
          select id + counter
          from numbers;
      select count(*) into counter from numbers;
      select counter;
  end while;
end $$
delimiter ;

call fill_numbers();
Even without a stored procedure, you could just insert a line manually and then execute 20 times this query:
insert into numbers (id) select id + (select count(*) from numbers) from numbers; select count(*) from numbers;
And it should not take you more than 30 seconds.
words
If your case calls for a large list of unique words, you could of course build it with a program, but then again the insertion process would be quite slow to complete. A faster method is to load an existing list from as file.All Unix system include a word list, whose size ranges from a few thousand to half a million. If you don't have such a list available in your box, you can get one (or build it from several ones) from several places. Good places to start looking for words are this and this.
At the end of the exercise, let's say that you've got a list of about half a million distinct words in /usr/share/dict/words. Thus, you can proceed to build your table.
drop table if exists words;
create table words (
  id int not null auto_increment primary key,
  t varchar(50) not null
);

load data local infile '/usr/share/dict/words'
  into table words (t);

Query OK, 518584 rows affected (4.94 sec)
Records: 518584  Deleted: 0  Skipped: 0  Warnings: 0

select count(*) from words;
+----------+
| count(*) |
+----------+
|   518584 |
+----------+
1 row in set (0.04 sec)
Since we need unique words, we can ask the database to produce the missing half by reversing the existing ones.
insert into words (t) select reverse(t) from words;
Query OK, 518584 rows affected (3.98 sec)
Records: 518584  Duplicates: 0  Warnings: 0

select count(*) from words;
+----------+
| count(*) |
+----------+
|  1037168 |
+----------+
alter ignore table words add unique key (t);
Query OK, 1037168 rows affected (46.69 sec)
Records: 1037168  Duplicates: 5791  Warnings: 0

select count(*) from words;
+----------+
| count(*) |
+----------+
|  1031377 |
+----------+
dates
Finally, let's see how to create a large list of dates. Actually, you would seldom need a million dates, since a million days cover more than 2,700 years. A table of just dates, thus, will usually range from 1,000 to 10,000 records. When you need a million records, you are more likely talking about DATETIME values, with intervals of hours, minutes, or seconds. Nothing will prevent you from using this technique to create one thousand DATE values, but let's keep to our original goal of filling a large table.Then, if we want records with one minute interval, we can proceed like this:
drop table if exists dates;
create table dates (
  id int(11) not null auto_increment primary key,
  dt datetime not NULL
) engine=myisam;

delimiter $$

drop procedure if exists make_dates $$
CREATE PROCEDURE make_dates( max_recs int)
begin
  declare start_dt datetime;
  declare numrecs int default 1;
  set start_dt = date_format( now() - interval max_recs minute, '%Y-%m-%d %H:%i:00');

  insert into dates (dt) values (start_dt );

  while numrecs < max_recs
  do
      insert into dates (dt)
          select dt + interval ( numrecs ) minute
          from dates;
      select count(*) into numrecs from dates;
      select numrecs;
  end while;
end $$

delimiter ;
Only this time we use the record count to calculate the interval in minutes between the existing records and the ones being inserted.
Also in this case, we double the table 20 times, to pass the one million records mark.
call make_dates( 1000000 );
+---------+
| numrecs |
+---------+
|       2 |
+---------+
1 row in set (0.02 sec)

+---------+
| numrecs |
+---------+
|       4 |
+---------+
1 row in set (0.02 sec)

# ... 16 more counts

+---------+
| numrecs |
+---------+
|  524288 |
+---------+
1 row in set (5.99 sec)

+---------+
| numrecs |
+---------+
| 1048576 |
+---------+
1 row in set (10.18 sec)

select count(*), min(dt), max(dt) from dates;
+----------+---------------------+---------------------+
| count(*) | min(dt)             | max(dt)             |
+----------+---------------------+---------------------+
|  1048576 | 2004-07-07 13:57:00 | 2006-07-05 18:12:00 |
+----------+---------------------+---------------------+
There are other techniques as well, but these three are techniques that you can use to get the job done even without dedicated tools.
Wednesday, May 24, 2006
Tutorial for a more powerful MySQL Sandbox
The MySQL Sandbox has been enhanced, with a new express installer, capable of setting up a sandbox in just a few seconds, and an interactive wizard, for fine tuning complex installations.
A lengthty tutorial is accompanying the new release.
This tool could be the basis for a long overdue interactive installation tool for Unix systems. What do you think?
A lengthty tutorial is accompanying the new release.
This tool could be the basis for a long overdue interactive installation tool for Unix systems. What do you think?
Sunday, May 14, 2006
New homes

I have a new web site. I registered the datacharmer.org and datacharmer.com domains, which are now jointly my main page. (Both addresses point to the same page)

Another change involves the MySQL General Purpose Stored Routines Library, which has evolved to version 1.0 (not alpha anymore). Its home is now at SourceForge.
Wednesday, April 26, 2006
MySQL Community Awards
Second day of the MySQL USers Conference 2006.
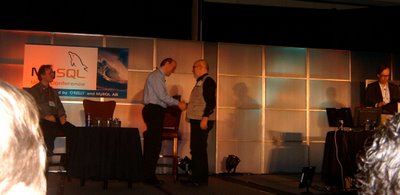
At breakfast, Arjen approached me, asking if I could hang nearby the podium during the keynote. "You may end up on stage", he said. I thought that they were going to hand me the iPod that was announced some time ago. So I went there and secured a seat as close as I could, together with Markus, Beat, Roland, and Sheeri.
However, instead of the iPod (I got it after lunch, BTW) I was called on stage to get a Community Award, and the same was granted to Roland, Markus, and Rasmus (!!)
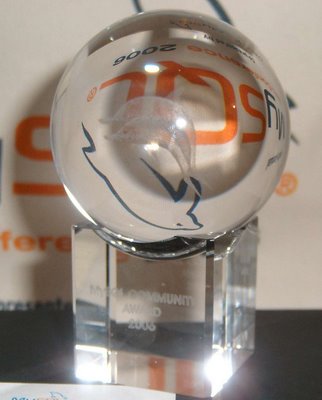
Looks quite useful. Now when somebody asks difficult questions, I can always consult the crystal ball. :)
Thanks to the MySQL Community for this wonderful surprise, and congratulations to Roland, Markus, and Rasmus!
(Pictures courtesy of Roland. Thanks)
At breakfast, Arjen approached me, asking if I could hang nearby the podium during the keynote. "You may end up on stage", he said. I thought that they were going to hand me the iPod that was announced some time ago. So I went there and secured a seat as close as I could, together with Markus, Beat, Roland, and Sheeri.
However, instead of the iPod (I got it after lunch, BTW) I was called on stage to get a Community Award, and the same was granted to Roland, Markus, and Rasmus (!!)
Looks quite useful. Now when somebody asks difficult questions, I can always consult the crystal ball. :)
Thanks to the MySQL Community for this wonderful surprise, and congratulations to Roland, Markus, and Rasmus!
(Pictures courtesy of Roland. Thanks)
Tuesday, April 25, 2006
Talk at the MySQL UC: Higher Order MySQL
From the highly unorthodox department, a speech about stored routines that create other routines in MySQL.
Friday, April 21, 2006
Advanced replication techniques in MySQL 5.x

OnLamp has just published an article I wrote about some interesting things you can do with MySQL 5.x and replication.
- You can create an array of peer-to-peer nodes that are at the same time master and slave, without much worry about insertion conflicts, thanks to some server variables introduced in MySQL 5.0;
- You can achieve automatic failover using a combination of federated tables (MySQL 5.0) and events (5.1)
If you want to get your hands dirty, using the companion package MySQL Replication Playground you can try out the goodies described in the article without risking your valuable servers.
Comments welcome.
Introducing MySQL 5 Replication Playground
As promised when I talked about the MySQL Sandbox and as mentioned in this (very) recent article on replication, I have released a testing environment for replication, called the MySQL 5 Replication Playground.
It's a package that creates in one single server an array of four replicating nodes using MySQL 5.0 or 5.1. The purpose of this package is to help developers and administrators when they need to test applications involving replication. You don't need to use several boxes. One machine is enough. With just one instance of MySQL installed, the Replication Playground will install four data directories and it will create the necessary scripts to start, stop, and using the nodes.
The installation comes in two flavors: standard (i.e. one master and three slaves, as usual) and circular (where each node is at once master and slave, as explained in the above mentioned article).
Once you install it, you can play with it and test your failover procedures, without worrying about your valuable production data. The playground works with separated ports and sockets, and it's completely independent from any other MySQL installation.
The docs in the distribution package contain also some sample sessions with both the standard and the circular installation.
The package requires:
- Linux, or FreeBSD (theoretically, it should work with any Unix flavor, but it has been tested only with Linux and FreeBSD)
- MySQL 5.0 or 5.1
- bash
- tar
- gzip
- Perl (for the installation)
- Optionally, you need the Perl DBI and DBD::mysql to run some test tools
Wednesday, April 19, 2006
Introducing MySQL Sandbox
Normal MySQL users are going through a flurry of announcements about new versions that make them salivate ath the thought of what can be done with these new goodies. In November, version 5.0 became generally available, thur ready for production, then version 5.1 entered beta.
Ah! It would be nice if I could just install the new versions and test them. Sometimes, though, you can't do that, because you don't have root access, or you have already an older MySQL server running.
For years, due to my consulting duties, I have maintained several non-conflicting, different versions of MySQL. I did that manually, using some scripts that I have developed and tuned over time. For me it is not a big hassle. I am used to the command line, I wrote the tools, I know what to take care of, it's easy. Not so for some of my co-workers, who need to use the same facilities but lack the same degree of confidence that I got with trial-and-error.
So finally I put together all I did for myself and transferred most of my own knowledge into a Perl script that can create a seamless installation of MySQl 5.0 or 5.1 without need of root access, and without disturbing (or being disturbed by) existing MySQL installations.
I called this tool the MySQL Sandbox and I put it on SourceForge.
With this package, achieving your goal of a separated testing installation is quite simple (provided that you are running Linux or some other Unix, that is):
The destination directory will also contain some shell scripts to start, stop, and use the test server.
Optionally, you can also change the default configuration file by specifying --my_file={small|large|huge} . The sandbox installer will try to locate the sample files from the basedir you indicated, and will merge the basic parameters into your destination file (my.sandbox.cnf)
Once the installation is over, you go to the newly created directory, and start the server:
It has been tested in several Linux boxes. Ideally, it should work on every Unix box. Read the docs, or try
Happy testing!
However, that is not the end of it. More goodies are coming in the next days. Stay tuned.
Ah! It would be nice if I could just install the new versions and test them. Sometimes, though, you can't do that, because you don't have root access, or you have already an older MySQL server running.
For years, due to my consulting duties, I have maintained several non-conflicting, different versions of MySQL. I did that manually, using some scripts that I have developed and tuned over time. For me it is not a big hassle. I am used to the command line, I wrote the tools, I know what to take care of, it's easy. Not so for some of my co-workers, who need to use the same facilities but lack the same degree of confidence that I got with trial-and-error.
So finally I put together all I did for myself and transferred most of my own knowledge into a Perl script that can create a seamless installation of MySQl 5.0 or 5.1 without need of root access, and without disturbing (or being disturbed by) existing MySQL installations.
I called this tool the MySQL Sandbox and I put it on SourceForge.
With this package, achieving your goal of a separated testing installation is quite simple (provided that you are running Linux or some other Unix, that is):
- Download the binaries for the version of MySQL you want to try, or follow Markus Popp's instructions and compile your own.
- Unpack MySQL binaries in a convenient place (for the sake of this example, let's say you put it under $HOME/binaries/5.1.10)
- Download the latest MySQL Sandbox package and unpack it.
- Run the install program, saying where are the binaries
$ ./install.pl --basedir=$HOME/binaries/5.1.10If you answer "Y", or just press ENTER, the sandbox will create a $HOME/mysql_sandbox directory, and a data directory under it, containing the minimum for your MySQL installation to work.
The MySQL 5 Sandbox, version 1.1 19-Apr-2006
(C) 2006 Giuseppe Maxia, Stardata s.r.l.
installing with the following parameters:
basedir : /home/gmax/binaries/5.1.10
binbash : /bin/bash
conf_file :
datadir_from : archive
db_password : datacharmer
db_user : datacharmer
force : 0
home_directory : /home/gmax
install_version : 5.1
my_file :
operating_system_user : gmax
sandbox_directory : mysql_sandbox
sandbox_port : 3310
verbose : 0
do you agree? ([Y],n)
The destination directory will also contain some shell scripts to start, stop, and use the test server.
Optionally, you can also change the default configuration file by specifying --my_file={small|large|huge} . The sandbox installer will try to locate the sample files from the basedir you indicated, and will merge the basic parameters into your destination file (my.sandbox.cnf)
Once the installation is over, you go to the newly created directory, and start the server:
$ ./start.shAfter that, using the new server is easy.
~/binaries/5.1.10 ~/mysql_sandbox
~/mysql_sandbox
sandbox server started
$ ./use.shAs you see, there is also a dedicated prompt that may remind you what you are using.
Welcome to the MySQL monitor. Commands end with ; or \g.
Your MySQL connection id is 1 to server version: 5.1.10-beta-max
Type 'help;' or '\h' for help. Type '\c' to clear the buffer.
mysql [localhost] {datacharmer} ((none)) > exit
It has been tested in several Linux boxes. Ideally, it should work on every Unix box. Read the docs, or try
$ ./install --help
Happy testing!
However, that is not the end of it. More goodies are coming in the next days. Stay tuned.
Sunday, April 16, 2006
SQL Easter egg
There is a tentative Obfuscated SQL contest with one entry by Kai Voigt.
Here's my take (requires MySQL 4.1 or later):
Enjoy!
SELECT CONCAT(CONV(536,8,20), LPAD(EXPORT_SET(1,'Y','N','',1), 3, "P"), CHAR(32), HEX(234), UNHEX(594939469*POW(3,2)))Not bad, but ... SQL without data ? Doesn't sound right.
Here's my take (requires MySQL 4.1 or later):
drop table if exists complex;
drop table if exists simple;
CREATE TABLE complex ( simple char(2), complex char(1)) ;
CREATE TABLE simple ( complex char(2), simple char(1));

INSERT INTO complex VALUES ('0','7'),('1','6'),('2','6'),('3','6'),('4','2'),
('5','7'),('6','7'),('7','7'),('8','6'),('10','7'),('11','7'),('12','2'),
('13','7'),('14','6'),('15','6'),('24','2'),('25','6'),('26','6'),('27','6'),
('28','6'),('29','6'),('30','7'),('31','6');
INSERT INTO simple VALUES ('0','4'),('1','F'),('2','5'),('3','8'),('4','0'),
('5','2'),('6','1'),('7','3'),('8','A'),('10','3'),('11','5'),('12','0'),
('13','4'),('14','E'),('15','1'),('24','0'),('25','c'),('26','1'),('27','8'),
('28','b'),('29','3'),('30','2'),('31','5');
set @complex = sqrt(sqrt(0x19a1));
set @simple  = sqrt(sqrt(sqrt(0x290D741)));
select group_concat(unhex(concat(simple,complex))
order by complex.non_simple separator '' )
from (select simple ^ @complex non_simple, complex simple from complex) simple natural join
(select complex ^ @simple non_simple, simple complex from simple) complex ;
Enjoy!
Sunday, April 09, 2006
Sorting data by set of keys
This seems to be a popular problem, since I saw it twice in the past few weeks in two different newsgroups. Somebody complains that, having query with a set of keys like this
When I see such requests, I usually explain that there are two misconceptions. The first being that MySQL sorts results without asking. That it does not do, because a DBMS engine is basically lazy by design, and it won't do anything unless explicitly asked for. The second is that you are asking for a sort order in your set of keys. Such list is just an indication of which keys to consider for filtering the results, and it has no influence at all on ordering. If you want ordering, you need to say so explicitly, using the ORDER BY clause.
Once I clarified what the problem is, let's see the solutions.
You can sort it on-the-fly, if your values are reasonably few
SELECT * from mytable where id IN (200, 2 ,100)they get the results in a order that ius different from the one they specified. For example, they may get something like
selectOne of the posters complained that the result should come in the specified order [200,2,100], and that MySQL was arbitrarily sorting its resultset.
*
from
main_table
where
id in (200,2,100);
+-----+----------+
| id | contents |
+-----+----------+
| 2 | b |
| 100 | aa |
| 200 | bb |
+-----+----------+
When I see such requests, I usually explain that there are two misconceptions. The first being that MySQL sorts results without asking. That it does not do, because a DBMS engine is basically lazy by design, and it won't do anything unless explicitly asked for. The second is that you are asking for a sort order in your set of keys. Such list is just an indication of which keys to consider for filtering the results, and it has no influence at all on ordering. If you want ordering, you need to say so explicitly, using the ORDER BY clause.
Once I clarified what the problem is, let's see the solutions.
You can sort it on-the-fly, if your values are reasonably few
selectThis solution looks like a hack, and in fact it can negatively affect performance, and it is difficult to handle when you need to change the sort order. The best way is to use a support table providing the required sort order.
*
from
main_table
where
id in (200, 2, 100)
order by
case id
when 200 then 1
when 2 then 2
when 100 then 3
end ;
+-----+----------+
| id | contents |
+-----+----------+
| 200 | bb |
| 2 | b |
| 100 | aa |
+-----+----------+
create table sorting_table (Now to get the wanted order we use a join between the main table and the secondary one.
sort_order int not null auto_increment primary key,
fk_id int,
key (fk_id)
);
# here we insert the values in the order we want.
# the auto incremented key will insure that this is the correct one
insert into sorting_table (fk_id) values (200), (2), (100);
select * from sorting_table;
+------------+-------+
| sort_order | fk_id |
+------------+-------+
| 1 | 200 |
| 2 | 2 |
| 3 | 100 |
+------------+-------+
selectThis is a much better solution, which offers flexibility and efficiency at the same time.
main_table.*
from
main_table
inner join sorting_table on (id=fk_id)
where
id in (200,2, 100)
order by
sort_order ;
+-----+----------+
| id | contents |
+-----+----------+
| 200 | bb |
| 2 | b |
| 100 | aa |
+-----+----------+
Dumping MySQL information schema
I have been invited to join the O'Reilly weblogs on databases.
Today I gave my first contribution, with a piece on dumping MySQL information schema contents.
Today I gave my first contribution, with a piece on dumping MySQL information schema contents.
Sunday, April 02, 2006
Measuring replication speed
I am writing an article about some advanced replication features (coming soon), and I wanted to measure the speed of each specific architecture I am working with.
There seem to be no builtin MySQL solution for this particular problem, and thus I am using a hand made metrics tool, inspired by something that Jeremy Zawodny suggested in his High Performance MySQL a few years ago (see the relevant chapter on replication with code).
The naive method would be to set a timestamp in a master table, and to measure the same record when it shows up in the slave. Unfortunately, (but correctly, I have to say!) this does not work, because the binary log includes information on the current timestamp, so that master and slave in the end have exactly the same contents.
Using a trigger in MySQL 5.0 seems promising, because you can set the timestamp tothe value of SYSDATE(), thus showing the different insertion times in master and slave. However, MySQL imestamps precision is limited to seconds. Therefore, if I insert a record at 12:00:00.9999 and the slave receives it at 12:00:01.0001, MySQL will record a difference of 1 second, even though in this case the difference would be just a couple of milliseconds.
With this in mind, I worked on Zawodny suggestion, which was still dealing with seconds, to imrove the method and measure the performance of a replication system with a much better accuracy (possibly microseconds).
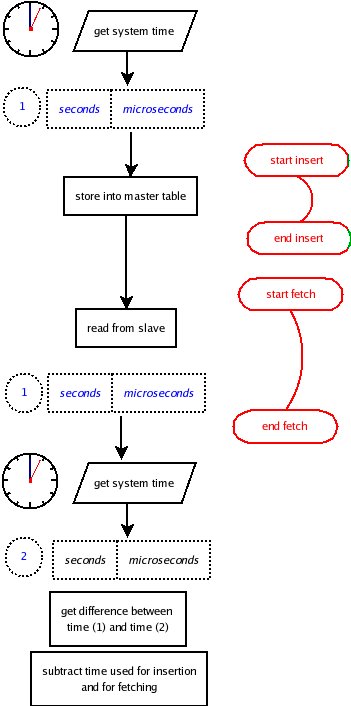
The schema works as follows (see the flow chart):
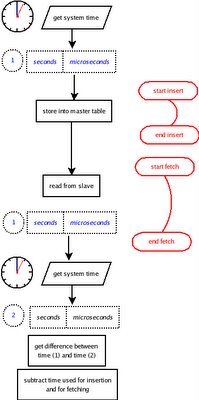
Get the system time in terms of seconds and microseconds (I am using Perl with the Time::HiRes module, but any major language has a corresponding feature). Insert that time in a table on the master, measuring also the time spent for the insertion operation.
Immediately after, start looping on the slave to get that same record. When you do it, get again the system time (with microseconds precision) and subtract the time you got from the table.
For better precision subtract the time you used for inserting and for fetching, and you get the bare replication time.
Here is an example, using a record of 1000 bytes, in a loop that increases the size of the record by 1000 bytes at each step.
This is the raw output used for debugging. The first colum is the step. The second is the ID retrieved from the record, the third one is the sequence number (I inserted 5 records for each steps, and asked to fetch the record with sequence no. 5).
The fourth and fifth columns are the system time that was stored in the table. The remaining two columns are the system time as recorded at fetch time.
With the above data, we can produce a listing of the actual raplication times, in human-readable format.
So the average replication time is, in this case, 0.001040 seconds.
For this test, I was using a sandbox environment, where both master and slave are in the same server. Thus there is some slight overhead due to the fact that one CPU is handling two instances of MySQL, and the same disk is hosting two logs (binary on the master, relay-log on the slave) in addition to the actual tables.
Using a real production replication, these times go down to an average of about 0.000500 seconds. It depends on several factors, from the speed of your networking equipment to the sheer power of your boxes.
Comments welcome.
There seem to be no builtin MySQL solution for this particular problem, and thus I am using a hand made metrics tool, inspired by something that Jeremy Zawodny suggested in his High Performance MySQL a few years ago (see the relevant chapter on replication with code).
The naive method would be to set a timestamp in a master table, and to measure the same record when it shows up in the slave. Unfortunately, (but correctly, I have to say!) this does not work, because the binary log includes information on the current timestamp, so that master and slave in the end have exactly the same contents.
Using a trigger in MySQL 5.0 seems promising, because you can set the timestamp tothe value of SYSDATE(), thus showing the different insertion times in master and slave. However, MySQL imestamps precision is limited to seconds. Therefore, if I insert a record at 12:00:00.9999 and the slave receives it at 12:00:01.0001, MySQL will record a difference of 1 second, even though in this case the difference would be just a couple of milliseconds.
With this in mind, I worked on Zawodny suggestion, which was still dealing with seconds, to imrove the method and measure the performance of a replication system with a much better accuracy (possibly microseconds).
The schema works as follows (see the flow chart):
Get the system time in terms of seconds and microseconds (I am using Perl with the Time::HiRes module, but any major language has a corresponding feature). Insert that time in a table on the master, measuring also the time spent for the insertion operation.
Immediately after, start looping on the slave to get that same record. When you do it, get again the system time (with microseconds precision) and subtract the time you got from the table.
For better precision subtract the time you used for inserting and for fetching, and you get the bare replication time.
Here is an example, using a record of 1000 bytes, in a loop that increases the size of the record by 1000 bytes at each step.
0    41     5   1143983120       992916   1143983120       997036
1    41     5   1143983121       207218   1143983121       211084
2    41     5   1143983121       420654   1143983121       424630
3    41     5   1143983121       634802   1143983121       638909
4    41     5   1143983121       849051   1143983121       853521
5    41     5   1143983122        65003   1143983122        67892
6    41     5   1143983122       279944   1143983122       282933
7    41     5   1143983122       493895   1143983122       498320
8    41     5   1143983122       710443   1143983122       715032
9    41     5   1143983122       927867   1143983122       932013
10    41     5   1143983123       145376   1143983123       149648
This is the raw output used for debugging. The first colum is the step. The second is the ID retrieved from the record, the third one is the sequence number (I inserted 5 records for each steps, and asked to fetch the record with sequence no. 5).
The fourth and fifth columns are the system time that was stored in the table. The remaining two columns are the system time as recorded at fetch time.
With the above data, we can produce a listing of the actual raplication times, in human-readable format.
loop data size master insert slave retrieval total repl. time bare time
---- --------- ------------- --------------- ---------------- ---------
1      1000      0.001655        0.000859         0.004120  0.001606
2      1000      0.001643        0.001268         0.003866  0.000955
3      2000      0.001505        0.000850         0.003976  0.001621
4      3000      0.001604        0.000849         0.004107  0.001654
5      4000      0.001943        0.000851         0.004470  0.001676
6      5000      0.001853        0.000981         0.002889  0.000055
7      6000      0.001964        0.000968         0.002989  0.000057
8      7000      0.003285        0.001081         0.004425  0.000059
9      8000      0.001431        0.000851         0.004589  0.002307
10      9000      0.003076        0.001012         0.004146  0.000058
11     10000      0.001282        0.001600         0.004272  0.001390
So the average replication time is, in this case, 0.001040 seconds.
For this test, I was using a sandbox environment, where both master and slave are in the same server. Thus there is some slight overhead due to the fact that one CPU is handling two instances of MySQL, and the same disk is hosting two logs (binary on the master, relay-log on the slave) in addition to the actual tables.
Using a real production replication, these times go down to an average of about 0.000500 seconds. It depends on several factors, from the speed of your networking equipment to the sheer power of your boxes.
Anyway, this is a tool that can be useful sometimes. You can get the source code from MySQL Forge snippets.
Update Since the Forge is being decomissioned, I add the source code here.
#!/usr/bin/perl
use strict;
use warnings;
use Data::Dumper;
use DBI;
use Time::HiRes qw/ usleep gettimeofday tv_interval/;
use English qw( -no_match_vars );

my $username1 = 'user1';
my $password1 = 'user2';
my $username2 = 'pass1';
my $password2 = 'pass2';
my $host1     = 'host_IP1';
my $host2     = 'host_IP2';
my $port1     = '3306';
my $port2     = '3306';

my $dbh1=DBI->connect("dbi:mysql:test;host=$host1;port=$port1",
                $username1, $password1,
                {RaiseError => 1})
         or die "Can't connect: $DBI::errstr\n";

my $dbh2=DBI->connect("dbi:mysql:test;host=$host2;port=$port2",
                $username2, $password2,
                {RaiseError => 1})
         or die "Can't connect: $DBI::errstr\n";

my $loops                =     10; # how many times we loop (with size increase)
my $num_of_inserts       =      5; # how many records we insert for each loop
my $initial_blob_size    =  1_000; # how big is the record we start with
my $replica_db           = 'test'; # which database we use for testing

my $master_dbh = $dbh1;
my $slave_dbh = $dbh2;

my ( $exists_db ) = $master_dbh->selectrow_array(qq{SHOW DATABASES LIKE '$replica_db'});
unless ($exists_db) {
    eval {$master_dbh->do(qq{CREATE DATABASE $replica_db}) };
    if ( $EVAL_ERROR ) {
        die "execution error $DBI::errstr\n";
    }
}

#
# creating the measurement table
#
eval {
    $master_dbh->do( qq{
        CREATE DATABASE IF NOT EXISTS $replica_db});
    $master_dbh->do( qq{
        USE $replica_db } );
    $master_dbh->do( qq{
        DROP TABLE IF EXISTS replica_speed });
    $master_dbh->do( qq{
       CREATE TABLE replica_speed (
        id int(11) NOT NULL auto_increment,
        insert_sequence int not null,
        seconds bigint(20) default NULL,
        microseconds bigint(20) default NULL,
        ts timestamp(14) NOT NULL,
        big_one longtext,
        PRIMARY KEY  (`id`),
        KEY insert_sequence (insert_sequence)
       )
    } );
};
if ($EVAL_ERROR) {
    die "table creation error $DBI::errstr\n";
}

#
# give some time to the table creation to get replicated
#
usleep(200_000);
my $insert_query = qq{
    INSERT INTO $replica_db.replica_speed
        (insert_sequence, seconds, microseconds, big_one)
       VALUES ( ?, ?, ?, ?) };
my $retrieve_query = qq{
    SELECT seconds, microseconds, id, insert_sequence
    FROM $replica_db.replica_speed
    WHERE insert_sequence = ?
};
my $slave_sth = $slave_dbh->prepare($retrieve_query);

#
# checking max_allowed_packet to make sure that we are not
# exceeding the limits
#
my ( undef, $master_max_allowed_packet) = $master_dbh->selectrow_array(
        qq{ SHOW VARIABLES LIKE "max_allowed_packet" } );

my ( undef, $slave_max_allowed_packet) = $slave_dbh->selectrow_array(
        qq{ SHOW VARIABLES LIKE "max_allowed_packet" } );

my $max_allowed_packet = $master_max_allowed_packet;
if ( $slave_max_allowed_packet < $master_max_allowed_packet) {
    $max_allowed_packet = $slave_max_allowed_packet;
}
my @results     = ();

LOOP:
for my $loopcount (0 .. $loops )
{
    usleep(200_000);

    #
    # let's start with an empty table
    #
    $master_dbh->do( qq{ TRUNCATE $replica_db.replica_speed } );

    my $size   = $initial_blob_size * ($loopcount || 1);
    if ($size > $max_allowed_packet) {
        $size  = $max_allowed_packet - 1000;
    }
    my $master_insert_time  = 0.0;
    my $big_blob            = 'a' x $size;

    #
    # inserting several records in the master
    #
    for my $sequence (1 .. $num_of_inserts ) {
        my ( $secs, $msecs ) = gettimeofday();
        $master_dbh->do($insert_query, undef, $sequence, $secs, $msecs, $big_blob);
        $master_insert_time = tv_interval( [$secs, $msecs],  [gettimeofday()]);
    }
    my $replication_delay     = 0;
    my $total_retrieval_time  = 0;
    my $baredelay             = undef;

    #
    # fetching data from the slave
    #
    RETRIEVAL:
    while ( ! $replication_delay ) # waiting for data to arrive from master to slave
    {
        my $retrieval_start_time = [gettimeofday()];
        $slave_sth->execute( $num_of_inserts);
        my $info                = $slave_sth->fetchrow_arrayref();
        my $retrieval_stop_time = [gettimeofday()];
        my $retrieval_time      = 0.0;
        $retrieval_time         = tv_interval(
                $retrieval_start_time,
                $retrieval_stop_time);
        next RETRIEVAL unless $info->[0];

        #
        # retrieval time is counted only after a successful fetch
        #
        $total_retrieval_time   += $retrieval_time;
        $replication_delay      = tv_interval( [$info->[0], $info->[1]], $retrieval_stop_time);
        $baredelay              = $replication_delay - $total_retrieval_time - $master_insert_time;
        printf "%4d %5d %5d %12d %12d %12d %12d\n",
            $loopcount, $info->[2], $info->[3] , $info->[0] , $info->[1] ,
            $retrieval_stop_time->[0], $retrieval_stop_time->[1];
    }

    push @results,
        {
            data_size             => $size,
            master_insert_time    => $master_insert_time,
            slave_retrieval_time  => $total_retrieval_time,
            replication_time      => $replication_delay,
            bare_replication_time => $baredelay,
        }
}

#
# displaying results
#
my @header_sizes = qw(4 9 13 15 16 9);
my @headers = ('loop', 'data size', 'master insert', 'slave retrieval', 'total repl. time', 'bare time');
printf "%s %s %s %s %s %s\n" , @headers;
printf "%s %s %s %s %s %s\n" , map { '-' x $_ } @header_sizes;
my $count = 0;
for my $res (@results)
{
    printf "%4d %9d %13.6f %15.6f %16.6f %9.6f\n" , ++$count,
        map { $res->{$_} }
            qw/data_size master_insert_time slave_retrieval_time replication_time bare_replication_time/;
}
Comments welcome.
Subscribe to:
Posts (Atom)


